
Inspect Production Variables Without Redeploying
Learn when logs, traces, and dynamic logs help inspect production variables without redeploying. Includes setup limits and a safe capture checklist.

To inspect production variables without adding logs and redeploying, first find the failing request. Then capture only the runtime state you need at an enabled capture point. Keep normal logs for event history and traces for the request path. Use dynamic logs for the values those signals did not record.
There is one setup limit. Your application must already run an SDK and capture point that can collect the target values. You can turn that prepared point on or off without another release. A new code location or missing SDK may require an initial deployment. This guide shows how to check that limit before an incident.
Choose the signal that answers the question
| Question | Start with | Why |
|---|---|---|
| What happened before the error? | Application logs | They record events you chose before the request ran. |
| Which service or dependency failed? | Distributed trace | It shows the request path and timed spans. |
| Why did this branch choose the wrong result? | Dynamic log | It captures selected runtime values at a prepared point. |
OpenTelemetry defines logs as event records and traces as request paths. Its context propagation guide explains how trace IDs connect work across services. Neither signal guarantees that a local variable was recorded. A trace can locate the failing span while leaving the branch condition unknown.
Dynamic logs answer that last question when the running application supports them. They collect bounded runtime state from a capture point. They are not a replacement for your normal log pipeline.
A five-step production inspection
Imagine that checkout requests sometimes apply the wrong discount. The existing logs show the final total. A trace points to the pricing service. Neither shows the selected rule or input category.
1. Identify one request and one decision
Find a representative failed request. Record its time, route, service version, trace ID, and result. Check a successful request for comparison. Choose the decision that could explain the difference, such as discount selection before the total is calculated.
Do not start by capturing every variable in every request. A narrow question keeps the result useful and limits exposure.
2. Check that the capture point is ready
Verify that the target service already runs a supported Tracekit SDK with code monitoring enabled. Check that a capture point exists at the decision, or that the deployed code calls a capture method there. The Tracekit code monitoring guide shows both setup paths. The Node.js guide and Python guide show language-specific setup.
No redeployment applies to prepared instrumentation. Tracekit's Node.js and Python SDKs receive values supplied to their capture methods. They do not promise access to every local variable at an arbitrary new source line. If the values or code location are missing, add the needed capture call and deploy it through your normal process first.
3. Limit what the point collects
Select only the values needed for the question. For the checkout example, these might be a rule identifier, a product category, and a boolean that explains eligibility. Avoid names, payment details, credentials, and raw request bodies.
Where supported, use a condition for the affected route or result. Set a maximum capture count and an expiration time. Confirm that the service kill switch is available. Review captured fields before you let a point run on high-volume traffic. Tracekit's dynamic logs feature describes the user-facing workflow.
Redaction helps, but it cannot prove that every sensitive value is safe to collect. Apply your own data policy before capture.
4. Trigger and compare
Run the same request path with a safe test input, or wait for the next matching request. Open the captured result and compare it with the trace and service version. Ask:
- Did the point fire in the expected service and release?
- Did the condition select the intended request?
- Which supplied value changed before the wrong result?
- Does the trace show a downstream failure instead of a local decision error?
- Does a successful request show the expected value at the same step?
One capture can reveal that the discount rule received the wrong category. It cannot prove why that category was wrong. Follow the input to its source before you change code.
5. Stop capture and record the result
Disable the point when you have enough evidence. Keep a short incident note with the trace ID, service version, captured field names, finding, and fix. Remove temporary capture code during a later cleanup if it has no ongoing use.
What to do when no capture point exists
A capture point cannot inspect a value that the running SDK does not supply. Use these options in order:
- Search existing logs and traces for a safe value that already answers the question.
- Check whether an existing instrumented capture point covers the decision.
- Add a narrow capture call or instrumentation to the next release when neither exists.
- Test the field list and redaction in staging before production.
- Keep a rollback path for any SDK or instrumentation change.
This setup step matters. “Without redeploying” describes an investigation with prepared instrumentation. It does not mean every application can expose every local value immediately.
Logs, traces, and dynamic logs work together
Use logs for durable event history. Use traces to locate the service and span. Use a dynamic log to inspect a small set of runtime values at the suspected decision. The production logs troubleshooting guide helps when an existing log line lacks context. The distributed tracing guide explains how to follow a request across services.
If you need values from many earlier requests, add structured application logs or another approved data source. A capture point only sees requests that hit it while it is active. If you need a new value at a new code location, plan an instrumentation release.
Quick checklist
- Find a failed request and its trace ID.
- Name the exact decision and values to inspect.
- Confirm that the SDK and capture point are already deployed.
- Exclude sensitive data and set capture limits.
- Compare a failed request with a successful request.
- Disable capture after the investigation.
- Record the evidence and test the fix.
Tracekit dynamic logs can capture selected runtime state on live traffic without stopping the service. Their value is strongest when logs and traces have already narrowed the question. Prepare the capture path before an incident, then keep each investigation small and bounded.
Related Posts
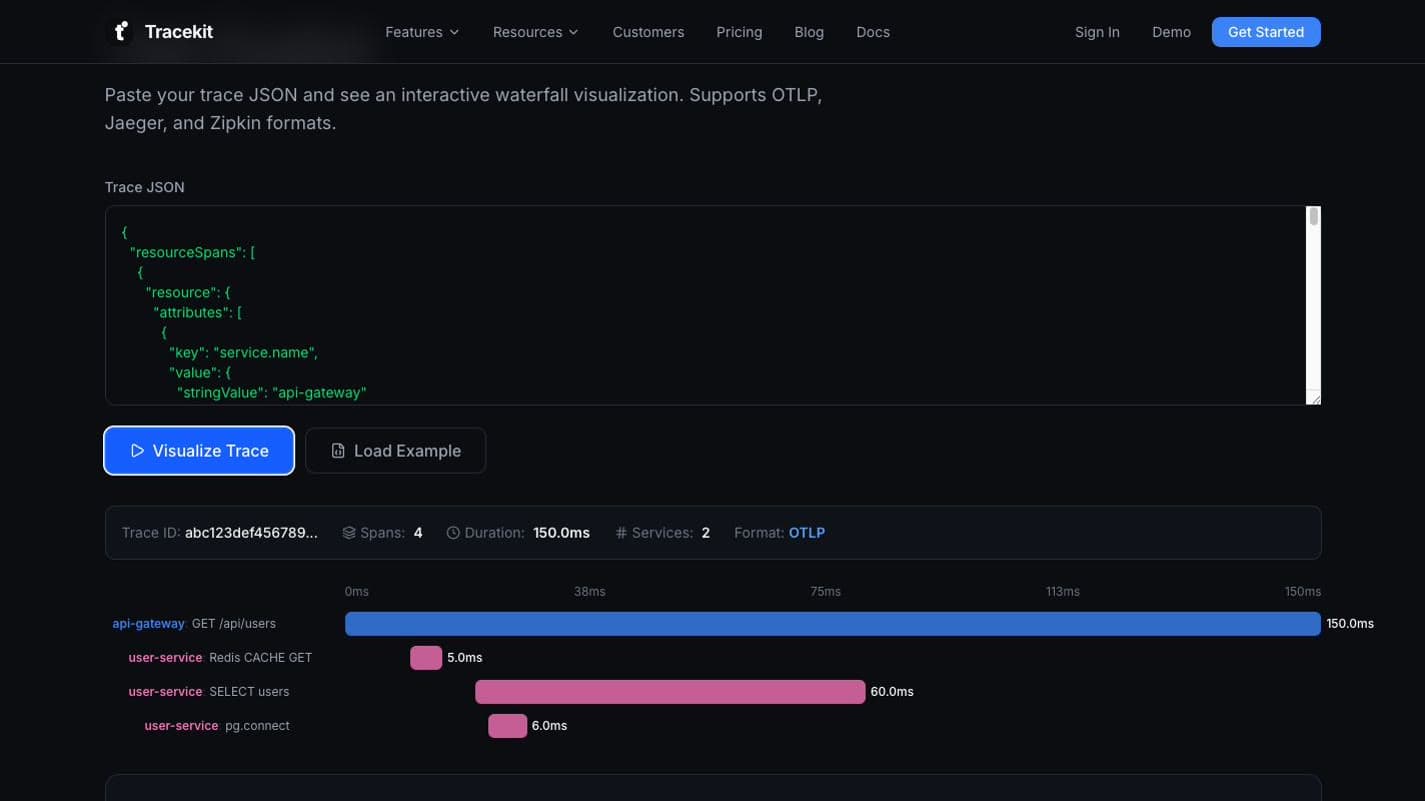
How to Visualize OpenTelemetry Traces Online
Visualize OpenTelemetry traces online, read the waterfall, fix export errors, and choose the right OTel trace viewer for each debugging job.
How to Debug Production APIs Without Logs
Debug production APIs without relying on logs. Use distributed tracing, dynamic logs, and AI anomaly detection to find root causes 70% faster.
5 Ways to Debug Production Apps Without Redeploying
Explore five innovative ways to debug production applications in real-time without redeploying, ensuring smooth user experiences.